परिचय
ऐसा लगता है कि दुनिया एक्सेल पर राज करती है। मैं अपने डेटा इंजीनियरिंग काम में यह देखकर आश्चर्यचकित हुआ हूं कि मेरे कितने सहकर्मी निर्णय लेने के लिए एक्सेल को एक महत्वपूर्ण उपकरण के रूप में उपयोग कर रहे हैं। जबकि मैं MS Office और उनकी एक्सेल स्प्रेडशीट्स का बड़ा प्रशंसक नहीं हूं, मैं फिर भी आपको बड़े एक्सेल स्प्रेडशीट्स को प्रभावी ढंग से संभालने का एक साफ ट्रिक दिखाऊंगा।
कैसे करें
प्रोग्राम में सीधे कूदने से पहले, पैंडास के साथ एक्सेल स्प्रेडशीट्स से निपटने के कुछ बुनियादी बातों को समझते हैं।
1. इंस्टॉलेशन
आगे बढ़ें और openpyxl और xlwt इंस्टॉल करें। अगर आप अनिश्चित हैं कि यह इंस्टॉल है या नहीं, तो पायथन टर्मिनल से pip freeze या pip list का उपयोग करके उपलब्ध पैकेज देखें।
2. टुपल डेटा पास करके एक्सेल स्प्रेडशीट बनाएं
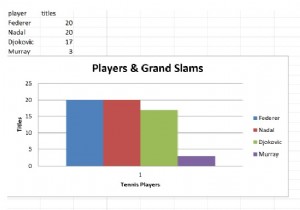
फिर हम डेटा को पैंडास डेटाफ्रेम में लोड करेंगे। अंत में हम डेटाफ्रेम डेटा को एक नई वर्कबुक में लिखेंगे।
import xlsxwriter
import pandas as pd
# फंक्शन: write_data_to_files
def write_data_to_files(inp_data, inp_file_name):
    """function: create a csv file with the data passed to this code
    args: inp_data: tuple data to be written to the target file
          file_name: target file name to store the data
    return: none
    assumption: File to be created and this code are in same directory."""
    print(f" *** Writing the data to - {inp_file_name}")
    workbook = xlsxwriter.Workbook(inp_file_name)
    worksheet = workbook.add_worksheet()
    row = 0
    col = 0
    for player, titles in inp_data:
        worksheet.write(row, col, player)
        worksheet.write(row, col + 1, titles)
        row += 1
    workbook.close()
    print(f" *** Completed writing the data to - {inp_file_name}")
# फंक्शन: excel_functions_with_pandas
def excel_functions_with_pandas(inp_file_name):
    """function: Quick overview of functions you can apply on excel with pandas
    args: inp_file_name: input excel spread sheet
    return: none"""
    data = pd.read_excel(inp_file_name)
    print(f" *** Displaying top 2 rows of - {inp_file_name} \n {data.head()}")
    print(f" *** Displaying info about {inp_file_name} - {data.info()}")

    # नई स्प्रेडशीट "Sheet2" बनाएं और उसमें डेटा लिखें
    new_players_info = pd.DataFrame(data=[
        {"players": "new Roger Federer", "titles": 20},
        {"players": "new Rafael Nadal", "titles": 20},
        {"players": "new Novak Djokovic", "titles": 17},
        {"players": "new Andy Murray", "titles": 3}
    ], columns=["players", "titles"])

    new_data = pd.ExcelWriter(inp_file_name)
    new_players_info.to_excel(new_data, sheet_name="Sheet2")
बड़े एक्सेल स्प्रेडशीट्स को चंक्स में प्रोसेस करना
बड़े CSV फाइलों से निपटते समय हमारे पास चंक्स सहित कई विकल्प होते हैं, हालांकि एक्सेल स्प्रेडशीट्स के लिए पैंडास डिफ़ॉल्ट रूप से चंक्स विकल्प प्रदान नहीं करता।
तो नीचे दिया गया प्रोग्राम काफी मददगार है अगर आप एक्सेल स्प्रेडशीट को चंक्स में प्रोसेस करना चाहते हैं।
def global_excel_to_db_chunks(file_name, nrows):
    """function: handle excel spreadsheets in chunks
    args: inp_file_name: input excel spread sheet
    return: none"""
    chunks = []
    i_chunk = 0
    # पहली पंक्ति हेडर है। हमने इसे पहले ही पढ़ लिया है, इसलिए हम इसे छोड़ देते हैं।
    skiprows = 1
    df_header = pd.read_excel(file_name, nrows=1)

    while True:
        df_chunk = pd.read_excel(
            file_name, nrows=nrows, skiprows=skiprows, header=None
        )
        skiprows += nrows

        # जब कोई डेटा नहीं है, तो हम जानते हैं कि हम लूप से बाहर निकल सकते हैं
        if not df_chunk.shape[0]:
            break
        else:
            print(f" ** Reading chunk number {i_chunk} with {df_chunk.shape[0]} Rows")
            chunks.append(df_chunk)
            i_chunk += 1

    df_chunks = pd.concat(chunks)
    # चंक्स को हेडर के साथ जोड़ने के लिए कॉलम्स का नाम बदलें
    columns = {i: col for i, col in enumerate(df_header.columns.tolist())}
    df_chunks.rename(columns=columns, inplace=True)
    df = pd.concat([df_header, df_chunks])
    print('*** Reading is Completed in chunks...')

if __name__ == '__main__':
    print(f" *** Gathering & Displaying Stats on the excel spreadsheet ***")
    file_name = 'Sample-sales-data-excel.xls'
    stats = pd.read_excel(file_name)
    print(f" ** Total rows in the spreadsheet are - {len(stats.index)} Rows")
    # एक्सेल फाइल को एक बार में 1000 पंक्तियों के चंक्स में प्रोसेस करें
    global_excel_to_db_chunks(file_name, 1000)
आउटपुट:
*** Gathering & Displaying Stats on the excel spreadsheet ***
** Total rows in the spreadsheet are - 9994 Rows
** Reading chunk number 0 with 1000 Rows
** Reading chunk number 1 with 1000 Rows
** Reading chunk number 2 with 1000 Rows
** Reading chunk number 3 with 1000 Rows
** Reading chunk number 4 with 1000 Rows
** Reading chunk number 5 with 1000 Rows
** Reading chunk number 6 with 1000 Rows
** Reading chunk number 7 with 1000 Rows
** Reading chunk number 8 with 1000 Rows
** Reading chunk number 9 with 994 Rows
*** Reading is Completed in chunks...