TensorFlow Google द्वारा प्रदान किया गया एक मशीन लर्निंग फ्रेमवर्क है। यह एक ओपन-सोर्स फ्रेमवर्क है जिसका उपयोग पायथन के साथ एल्गोरिदम, डीप लर्निंग एप्लिकेशन और बहुत कुछ लागू करने के लिए किया जाता है। यह शोध और उत्पादन उद्देश्यों के लिए उपयोग किया जाता है।
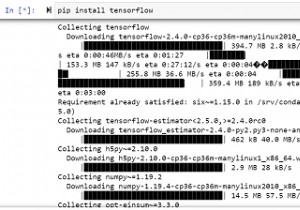
'tensorflow' पैकेज को Windows पर नीचे दिए गए कोड की लाइन का उपयोग करके इंस्टॉल किया जा सकता है:
pip install tensorflow
टेंसर TensorFlow में उपयोग की जाने वाली एक डेटा संरचना है। यह फ्लो डायग्राम में किनारों को जोड़ने में मदद करता है। इस फ्लो डायग्राम को 'डेटा फ्लो ग्राफ' के रूप में जाना जाता है। टेंसर बहुआयामी सरणी या सूची के अलावा कुछ नहीं हैं।
हम नीचे दिए गए कोड को चलाने के लिए Google Colaboratory का उपयोग कर रहे हैं। Google Colab या Colaboratory ब्राउज़र पर पायथन कोड चलाने में मदद करता है और इसके लिए शून्य कॉन्फ़िगरेशन और GPUs (ग्राफिकल प्रोसेसिंग यूनिट्स) तक मुफ्त पहुंच की आवश्यकता होती है। Colaboratory को Jupyter Notebook के शीर्ष पर बनाया गया है।
उदाहरण
निम्न कोड स्निपेट है:
print("1234 ---> ", int_vectorize_layer.get_vocabulary()[1289])
print("321 ---> ", int_vectorize_layer.get_vocabulary()[313])
print("Vocabulary size is : {}".format(len(int_vectorize_layer.get_vocabulary())))
print("The text vectorization is applied to the training dataset")
binary_train_ds = raw_train_ds.map(binary_vectorize_text)
print("The text vectorization is applied to the validation dataset")
binary_val_ds = raw_val_ds.map(binary_vectorize_text)
print("The text vectorization is applied to the test dataset")
binary_test_ds = raw_test_ds.map(binary_vectorize_text)
int_train_ds = raw_train_ds.map(int_vectorize_text)
int_val_ds = raw_val_ds.map(int_vectorize_text)
int_test_ds = raw_test_ds.map(int_vectorize_text)
कोड क्रेडिट - https://www.tensorflow.org/tutorials/load_data/text
आउटपुट
1234 ---> substring
321 ---> 20
Vocabulary size is : 10000
The text vectorization is applied to the training dataset
The text vectorization is applied to the validation dataset
The text vectorization is applied to the test dataset
व्याख्या
अंतिम प्रीप्रोसेसिंग चरण के रूप में, 'TextVectorization' लेयर को प्रशिक्षण डेटा, टेस्ट डेटा और वैलिडेशन डेटासेट पर लागू किया जाता है।